Bring Real-Time Data to Your Data Lakehouse and AI
Stream data from legacy and modern systems, making fresh, governed data available to your lakehouse without building separate pipelines for every use case.
Streamhouse + Lakehouse: Better Together
Your lakehouse is built for analytical workloads. Your Streamhouse keeps changing business data current, governed, and ready for real-time action.
Together, they connect operational and analytical data—so AI agents, applications, and analytics can work with trusted business context without requiring every workload to pass through a centralized analytical store.
Eliminate data silos. Do away with outdated, inefficient workflows that silo data from low throughput and high throughput sources, eliminating costly and difficult-to-manage replication of data.
Free your data. Ensure interoperability across clouds, warehouses, query engines and open-source data processing frameworks.
Scale performance, not cost. Cut your data infrastructure costs by 50% or more compared to traditional data platforms by running workloads incrementally on highly optimized compute.
Build with Confluent
This use case leverages the following building blocks in Confluent Cloud:
Reference Architecture
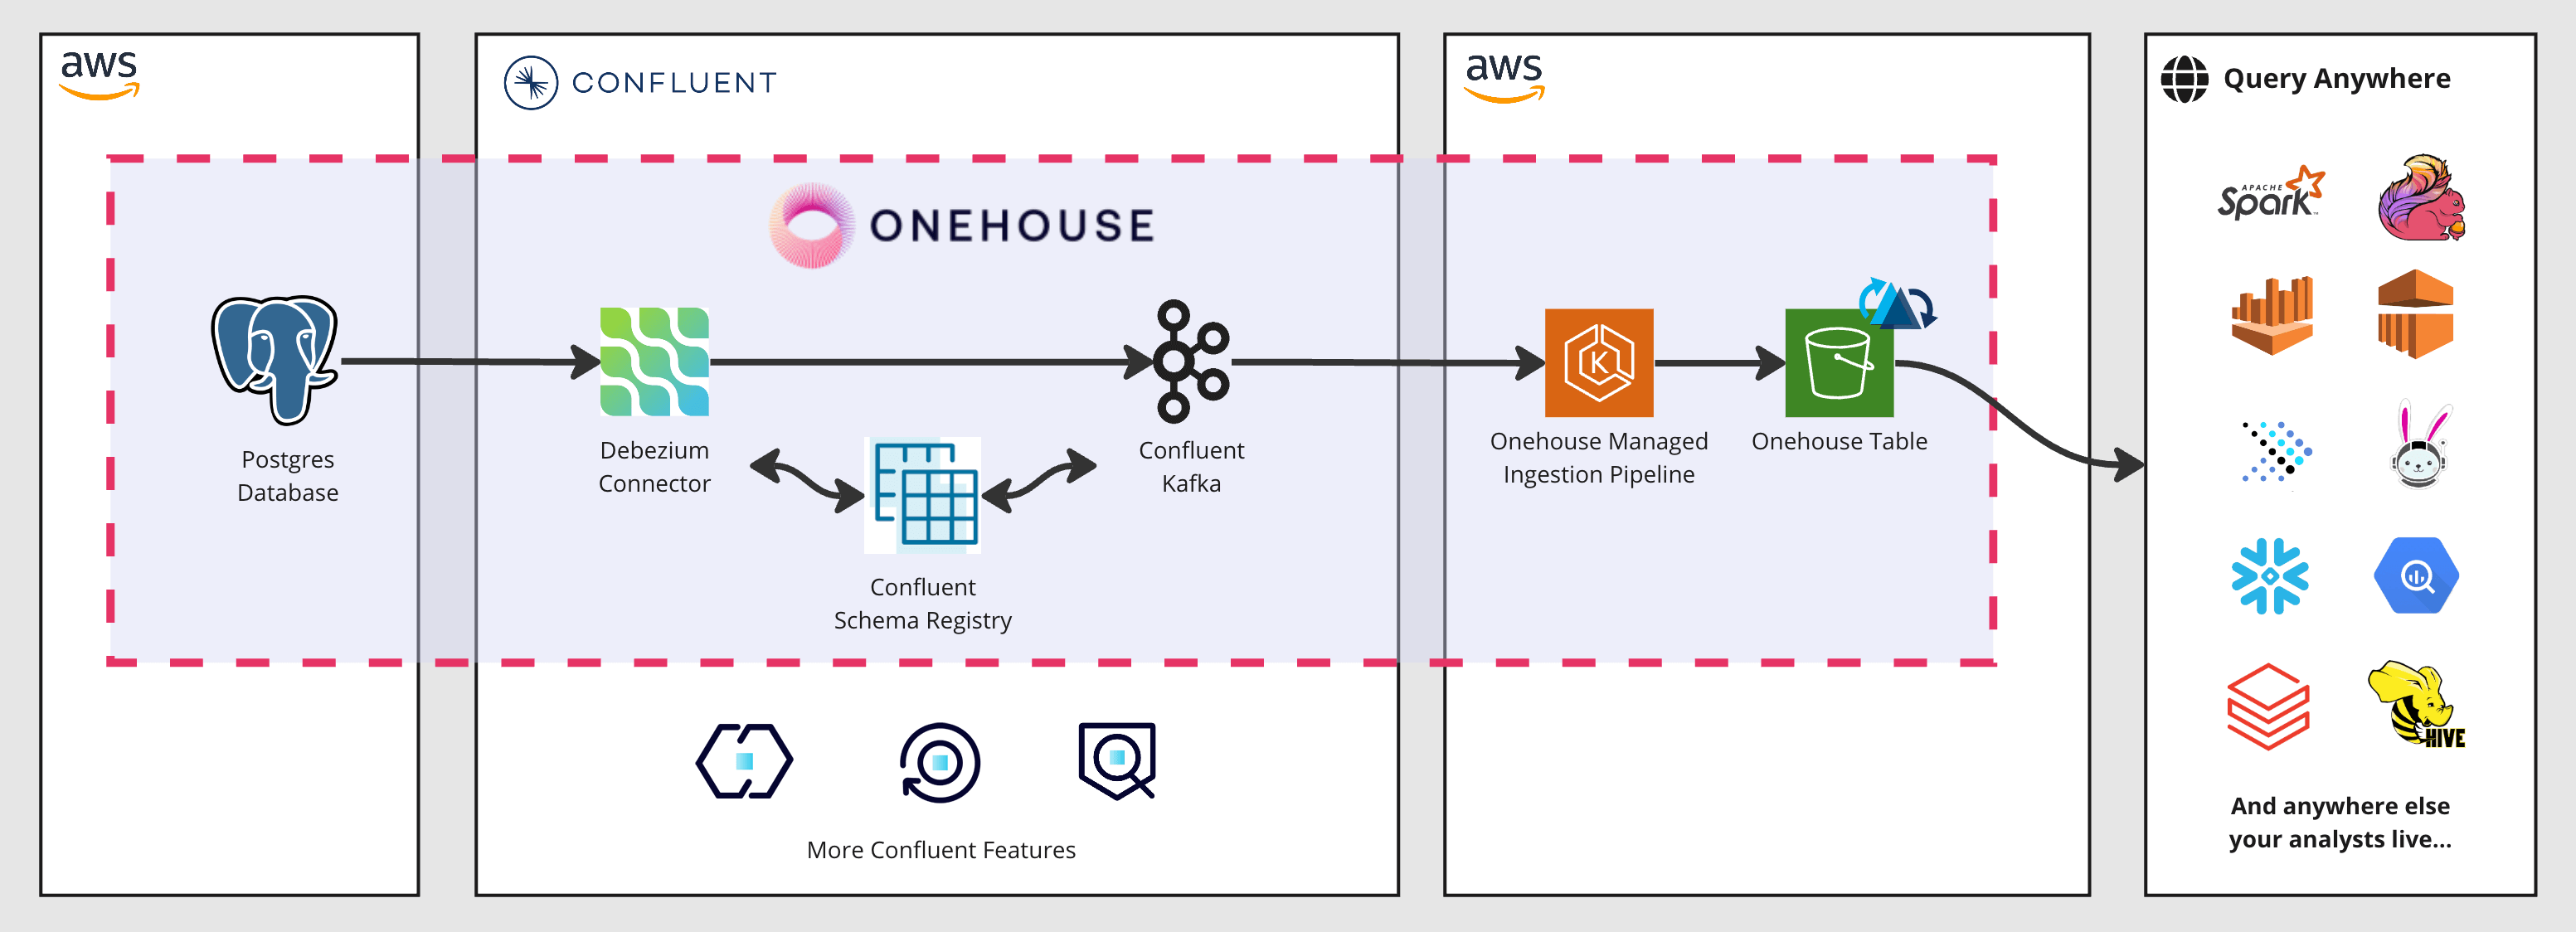
In this example, we are replicating a PostgreSQL database on AWS to the Onehouse Universal Data lake with a Debezium Connector and Confluent Kafka with up-to-the-minute data freshness.
Debezium is an open-source distributed platform for change data capture (CDC).
Onehouse automatically creates a new schema with Confluent’s Schema Registry (Stream Governance). Onehouse manages the Debezium connector, Confluent, and the schema to optimize cost and reduce engineering overhead.
Onehouse will ping PostgreSQL for any inserts, updates, and deletes at the interval you’ve set for up-to-the minute data. You can perform transformations such as masking and deduplication as part of your pipelines, and Onehouse enables you to create validations and quarantine suspicious data, so you can ensure data quality at the point of ingestion.
Onehouse integrates with a number of data catalogs so you can query and process your data downstream with the best tool for the job.